
Case study Part 2 of 4 · why a game
Why a game is a good teacher
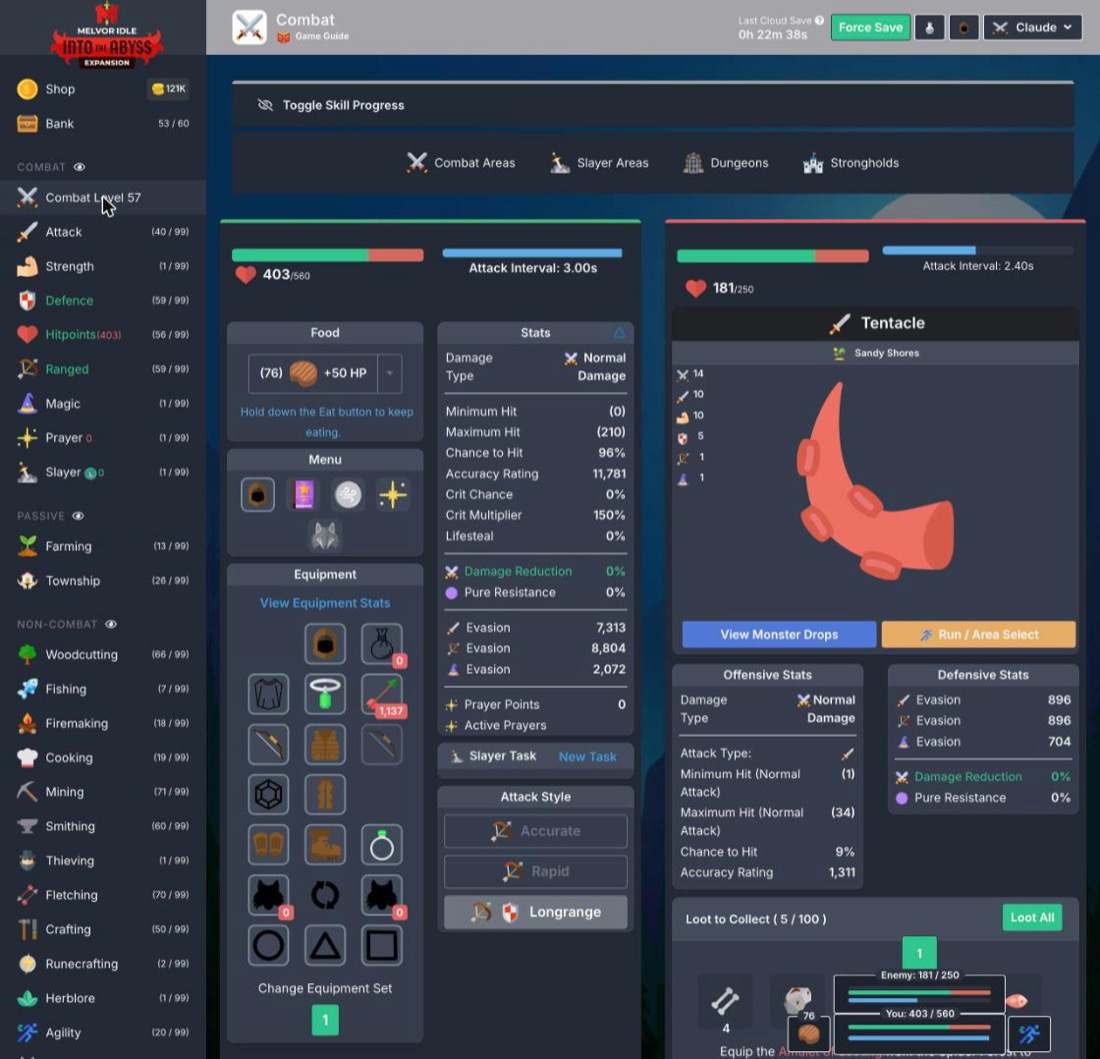
A cascade is a claim about where each decision belongs. To learn where things belong you need many decisions, fast feedback, and a safe place to be wrong. An idle game has all three, plus the messy browser failures that real agents meet. This page explains why Melvor Idle turned out to be a good place to learn the pattern, and where it stops being one.
Eight properties that make it work
1. Most decisions have computable answers
XP per hour, XP per material, gold per item, arrows per kill, food per arrow, inputs for a 1,000-unit run: the game exposes every number. That makes it easy to see when a judgment model or an LLM is wasted. If code can compute the answer, the question moves down to code.
Example: "which monster to train on" started as a judgment and became a damage-per-arrow model, then a measured XP-per-arrow log.
2. A residue of real judgment remains
Some questions have no formula: is this target worth working on now or later, is this item likely to be useful to the plan, would a careful player object to this move. Those are exactly the bounded calls a decision model is for. They stay with Jev, phrased narrowly and scored per option.
3. Volume makes tier rates measurable
The loop decided 935 times in six days, and every tick was logged with its state, questions, answers and decision. At that volume you can count things: how often code policies decide (about 23% of ticks), where novelty and doubt sit (median 0.46 and 0.38), how many readings cross the 0.7 line (7 of about 1,690). A handful of decisions would only give you anecdotes.
4. Mistakes are cheap and reversible
A wasted batch costs minutes; a bad sale costs a little gold. That makes it safe to let the lower tiers act rather than gating everything on review. You find the planner's blind spots by watching it run, not by imagining them.
5. Real environment failures happen
A background tab gets throttled and fights stall. A narrow window switches the game to its mobile layout and buttons move. A new tab steals focus. A save button click misses and nobody notices for four hours. These are not simulated; each one became a watcher event or a code fix.
6. Clear outcomes give verifiable feedback
Did the bar count go up? Is the bow worn? Did the gold go down after a purchase? Every action has an observable effect within seconds. So verification can check outcomes, not starts, and a failed check is a precise error report rather than a vague sense that something went wrong.
7. Natural human-only lines
The game sits inside things that are clearly not the agent's: real money (the game has paid content), the account and its settings, the owner's own save slot, and the owner's preferences about how the character should play. Those lines are easy to state and easy to keep, which makes the top of the cascade unambiguous.
8. Long horizons need planning, not just reflexes
Goals take hours to days, and every goal feeds others: arrows need bars, bars need coal, coal needs mining time. That gives the LLM a real job above the decision model (writing milestones, auditing plans, fixing the planner) without putting it in the hot path.
What the testbed taught that a benchmark couldn't
- The decision model can't see planner gaps. Most bad plans reached Claude with doubt at only 0.19–0.50. Jev judged the options it was given, and the option generator was at fault. You only learn this by running a planner for days. See part 4.
- LLM wakes are the scarce resource. Batch and restock sizes set how often Claude has to wake. A fixed batch of 120 meant about 12 rounds to one target; sizing it to the remaining need cut that to about 4.
- Sub-threshold readings carry signal. Doubt sitting at 0.60–0.63 three ticks in a row pointed to a contradiction in the playbook. A fixed 0.7 gate would never have reported it.
- Safety belongs in the fastest tier. A Cow took the character from 102 HP to 6 between two LLM wakes. The in-page guard, which checks every second, exists because of that.
Same pattern, different stakes: Melvor against the email project
The other project on this site is an email first pass over a personal inbox. It uses the same cascade shape, with code, Jev, the LLM and a person. The stakes put the weight in different places:
| Melvor agent | Email first pass | |
|---|---|---|
| What a decision does | Acts: starts a job, buys, sells, equips, clicks | Sorts: decides how much LLM and human attention a message gets |
| Cost of a mistake | Minutes or a little gold; almost always reversible | A missed obligation (a deadline, a failed payment) can be costly and is noticed late |
| Feedback | Seconds: the count went up or it didn't | Weeks: blind labels on held-out months |
| Code's role | Large: planner, policies, verification, a 1-second guard | Rules run beside the model and add facts; they may only keep mail out of the zero-token buckets |
| Jev's role | Priorities and worth-it calls on every tick, plus novelty and doubt | Concept detection (deadline, payment, waiting on a reply) as features for a learned sorter |
| How it's measured | Tier rates, doubt distributions, escalations and their fixes | AUCs per concept and the share of mail filtered at a fixed number of missed actions (58.9% at 1 miss) |
| The human tier | Thin: money, accounts, preferences, the visible window | The point: misses go to the person, so the threshold is set by how many they'll tolerate |
The game is where you learn the mechanics: what to push down, how to phrase questions, how to read doubt, how to keep wakes rare. Email is where you learn the stakes: holding out data, blind labels, and thresholds set by what a miss costs. A cascade for real work needs both lessons.
Where a game falls short. Reversible mistakes make it easy to be brave. In a domain where an error can't be undone, the same design needs a stricter gate at each tier, outcome checks before the action as well as after, and a human tier that is the default for anything new, not the exception.
Next: The Melvor cascade, built: the per-tick flow, the guard, the questions Jev answers and how escalation works, in color-coded pseudo-code.